Wednesday, July 13, 2011

Syntax Highlighting your Blog with highlight.js

I've had some people ask me how I got syntax highlighting for Smalltalk code on my blogger blog. Here's what I did:

  1. Download highlight.js

    Go to Software Maniac's download page. Turn off the languages you're not interested in. Check the checkbox for Smalltalk. And hit the download button. You'll get a zip file that when unarchived has a whole directory structure of files, including the customized highlight.js file for your efforts. You need this customized version because it doesn't support Smalltalk in the stock version.

  2. Host it somewhere

    Find a net presence to host it at. Hopefully, you've either got your own or know someone who can host it for you. I was fortunate to fall into the second category.

  3. Update your blog template

    Edit your blog template (in Edit HTML link under the Design tab of your blog. You add the following lines near the end of your template

    <script src="http://yourhostedsite/highlight.pack.js" type="text/javascript">
    <script type="'text/javascript'">
    hljs.initHighlightingOnLoad();
    </script>

    You need to edit the yourhostedsite part appropriately.

  4. Add additional CSS for your blog

    You need to choose a css style you like from the downloaded package's style directory. Then use Design -> Template Designer -> Advanced -> Add CSS (at the bottom) and paste the contents of your preferred styles .css file into that.

  5. Enclose code blocks appropriately

    To have the highlighter apply to a chunk of code, you place your code in between pre and code tags. E.g.

    <pre><code>
    ...smalltalk code snippets...
    </code></pre>

At least... that's how I remember how I did it. It's been a month or so now. Hope that helps. And would love to hear of errors/corrections in the above.

Making Performance Comparison Charts

My last post was submitted just before embarking on a multi-week multi-state driving family vacation. While I was gone, I received a couple of requests regarding the code actually used to draw the performance comparison charts in that post.

I used CairoGraphics to do it. Those that know me are likely not surprised by this. The code is just a big workspace blob, and is somewhat procedural.

One of the challenges I wrestled with was how to turn numbers the numbers into percent increase or decreases. The easy method of just dividing one value by the other gives values that are not linear when drawn graphically. Or put another way, that is twice as fast draws differently than something that is twice as slow.

I used this fun snippet to convert from aTime and bTime values into such a comparison:


(((originalTime max: newTime) /
(originalTime min: newTime)) - 1.0) * (originalTime - newTime) sign


The large workspace blob that works with a variable called percents follows below, I put comment annotations to delineate the various sections. It may serve as a useful Cairo snippet.


| max min surface bandHeight xInc text extents y |

"compute some dimensions and create the surface"
max := (percents fold: [:a :b | a max: b]) ceiling max: 0.
min := (percents fold: [:a :b | a min: b]) floor min: 0.
surfaceHeight := (max - min) * 75 min: 300.
bandHeight := surfaceHeight / (max - min).
surface := ImageSurface format: CairoFormat argb32
extent: 600 @ surfaceHeight.
xInc := surface width / percents size.

surface newCairoContextWhile:
[:cr | | matrix |

"setup a default font"
cr
selectFontFace: 'Arial'
slant: FontSlant normal
weight: FontWeight bold.

"flip the coordinate system so we draw from the bottom up, rather than normal y is down style"
cr fontSize: 11.
cr translate: 0 @ surface height.
cr scale: 1 @ -1.
matrix := cr fontMatrix.
matrix scale: 1 @ -1.
cr fontMatrix: matrix.

"do rounded clip/border"
cr rectangle: (Point zero corner: surface extent) fillet: 10.
cr clipPreserve.
cr source: ColorValue black.
cr fill.

"shift up to base line"
cr translate: 0 @ min * bandHeight negated.

"draw columns"
percents keysAndValuesDo:
[:size :percent |
| rectangle baseHue x |
cr saveWhile:
[cr
rectangle: (Point zero
extent: surface width @ (percent positive ifTrue: [max] ifFalse: [min])
* bandHeight)
regular.
cr clip.
rectangle := Rectangle
left: (size - 1) * xInc + 3
right: size * xInc - 3
top: 5
bottom: -5.
percent > 0
ifTrue: [rectangle top: percent * bandHeight]
ifFalse: [rectangle bottom: percent * bandHeight].
cr rectangle: rectangle regular fillet: 5.
baseHue := (1 / 6 + (percent / 3) min: 1 / 3) max: 0.
cr source: (ColorValue hue: baseHue saturation: 1 brightness: 0.85).
cr fillPreserve.
cr source: (ColorValue hue: baseHue saturation: 0.85 brightness: 1).
cr strokeWidth: 4.
cr stroke].

"draw the column label"
text := size printString.
size = 1 ifTrue: [text := 'size=' , text].
extents := cr textExtents: text.
x := (size - 0.5) * xInc - extents width half.
y := percent positive ifTrue: [extents height negated - 2] ifFalse: [2].
y := y max: min * bandHeight + 2.
cr moveTo: x @ y.
cr source: ColorValue white.
cr showText: text].

"draw axis lines"
min to: max
by: 1 / 2
do:
[:n |
cr moveTo: 0 @ (n * bandHeight).
cr lineTo: surface width @ (n * bandHeight)].
cr source: ColorValue white.
cr strokeWidth: 0.25.
cr stroke.

"draw axis"
cr source: ColorValue white.
min to: max
do:
[:n |
n isZero
ifFalse:
[text := (n + n sign) printString , 'x'.
extents := cr textExtents: text.
y := ((n * bandHeight max: min * bandHeight + 4 + extents height half)
min: max * bandHeight - 4 - extents height half) - extents height half.
cr moveTo: 4 @ y.
cr showText: text.
cr moveTo: (surface width - 4 - extents width) @ y.
cr showText: text]].
cr moveTo: Point zero.
cr lineTo: surface width @ 0.
cr strokeWidth: 1.
cr stroke.

"draw label"
text := '#at:put: - Chain vs CompactDictionary'.
extents := cr textExtents: text.
cr moveTo: (surface width half - extents width half)
@ (max * bandHeight - 4 - extents height).
cr showText: text].

"write the file"
surface writeToPng: 'chart.png'

Thursday, June 23, 2011

Kicking the Hash out of Dictionary

What Led to This Post

First of all, it was that I needed a break. I've been working on ARs, doing some embedded Linux stuff, working on Skinned Scrollbars, and Uniscribe at the same time. So yesterday afternoon, I thought I'd like to take a little journey.

One of the patterns that has become kind of popular in VisualWorks of late is the "Properties Dictionary". There are some drawbacks to them, but one of advantages is they allow for a sort of "poor man's instance variable pool." Using them, one can store state by by name, in a structure that isn't quite as established as standard instance variables. Package's use them. Various parts of the RB use them. VisualPart's use it.

These dictionaries have a similar usage pattern. They tend to be smaller in size. Their primary usage tends to be at:(ifAbsent:) and at:put:, where the keys are usually someone constant. Or in other words, the majority of the time, at:put: is replacing an existing value, rather than adding a new slot to the dictionary.

Which led to a bigger question even. Even without worrying about the consistency of keys, what about small dictionaries in general?

Are small dictionaries that common?

Here's a bit of code we can use to get a view on that question:


histogram := Bag new.
Dictionary allInstancesDo: [:each | histogram add: each size].
IdentityDictionary allInstancesDo: [:each | histogram add: each size].
histogram

Exporting the data and playing with GoogleDocs a bit, we come up with this:

At least in my image, smaller dictionaries actually take up more space then the large dictionaries (area under the red curve is greater than that of the blue curve). And obviously, there's a lot more of them than the larger dictionaries.

Another kind of analysis (which I did not do) would be to look at what the access rates of dictionaries are as a function of their size. In other words. Are we sending messages as often to the big dictionaries as we are the small ones?

Some Points of History

Seeing that optimizing smaller dictionaries is an interesting pursuit, is not a new idea. The original Refactoring engine sported a specialized RBSmallDictionary. It exploited the fact that for its use cases, the sizes were usually only one or two. The overhead of hashing, probing, etc wasn't really worth it for these usually-one-element dictionaries. Having their own, also allowed them have a specialized removeAll that was very fast.

When Steve Dahl added CompactDictionary for UCA, it looked close enough to RBSmallDictionary, that dropped RBSmallDictionary in favor of it. Both implementations are basically linear search dictionaries.

Over the last few releases, there have been a number of changes to hashing algorithms and Dictionary implementations in VisualWorks, primary instigated by Andres Valloud, which have changed the value of CompactDictionary/RBSmallDictionary as well. Take a look at the speed boost of CompactDictionary versus IdentityDictionary when sending #at: with Symbols as keys.
It's basically a draw at this point. The #at:put: story shows a moderate benefit for using a CompactDictionary over an IdentityDictionary when your size is 4 or less.

I'm told, that in the way-back-machine, VSE played games with optimizing small dictionaries. I don't have any more details than that though, and would love it if someone could speak truth to that rumor.

#at:(put:) Considered Harmful

The conventional wisdom to gain better dictionary performance is to work on hash algorithms. Make them faster. Make them separate better. Certainly that work will yield results. I think Andres's work has shown commendable efforts in those areas.

Sometimes we have to step out of our box and think about the problem from a different view point though. All of the improvements in hash algorithms ignore another important aspect of Smalltalk optimization. At the end of the day, all of this work on Dictionary will still result in the low level primitives for at: and at:put: running. Not the dictionary methods, but the one that is like the one found on array


anArray at: 4 put: anObject

The problem with this is that Smalltalk VM's want to be very safe. A bit of work is done every time the at:(put:) primitives fire. First, the VM wants to make sure you passed it an integer. And then it wants to convert your Smalltalk integer representation into a machine one. And then it wants to make sure that number is greater than one, and less than the current size of the variable sized receiver. That means it has to go fetch the current size first. And if that's all OK, then it wants to figure out what the real offset is from the header of the object. So it has fetch how many fixed fields it has first, and then add that to the offset. And now it can finally assign a pointer in the objects body to the object being stored at that slot. Oh yeah, there's a check in there to determine if size was really big, then the body of the object is in LargeSpace. You do this kind of work for every single at: and at:put: you do, whether indirectly or indirectly. A higher level Dictioanry>>at:put: will have to first compute a hash, then candidate insertion point, and then probe via a low level at: to see if it has a collision or existing value, and then eventually do an at:put: when it gets everything straightened out. And there's the overhead of just sending the message.


How much slower is indexed access than fixed variable access? It's easy to write a little snippet that will give us a hint


| point array index |
fixed := 3 @ 4.
array := Array new: 1000.
index := '888' asNumber.
[100000000 timesRepeat: [array at: index]] timeToRun asMicroseconds
asFloat / [100000000 timesRepeat: [point y]] timeToRun asMicroseconds

I get around 60% slower for VW 7.9 builds. But this is only a hint. It's not correct really. Because the point y expression doesn't just measure fixed var access, but also a message send. So in reality, the disparity is farther. I noodled about this for a while, I'm curious if anyone has a better way of comparing the two access methods in a truer measure. Basically, what we want to compare is the speed of the byte code to "push a known index" vs the speed of the #at: send.

A Dictionary with Fixed Slots

This is something I've wanted to try for a while. A linked list implementation where each link exposes a dictionary like interface. I tried to come up with a good name for this thing, and then gave up and called it Chain. It's actually implemented with two polymorphic classes. Here's what a Chain with two elements looks like

Chain and EmptyChain end up having the same basic set of methods. Both inherit from Collection. Most of the methods are a fun exercise in recursive programming. For example, here's the two #at:ifPresent: implementations


at: aKey ifPresent: aBlock
^key = aKey
ifTrue: [aBlock value: value]
ifFalse: [nextLink at: aKey ifPresent: aBlock]

and


at: aKey ifPresent: aBlock
^nil

In fact most of the EmptyChain methods do simple things like raise an error, return nil, return a copy, or do nothing. The two that are kind of fun are #at:put: and #removeKey:.

Chain #at:put:

The Chain implementation of #at:put: is simple:

at: aKey put: anObject
aKey = key
ifTrue: [value := anObject]
ifFalse: [nextLink at: aKey put: anObject].
^anObject

This will handle the cases where we already have aKey in our Chain and just want to update the value stored at that key. When we have a new key though, it will make it through to the EmptyChain implementation:

at: aKey put: anObject
| newLink |
newLink := Chain basicNew.
newLink setKey: aKey value: anObject next: newLink.
self become: newLink

There's a at least two interesting things going on here. The firs is that we use basicNew to instantiate a new Chain link. The reason is that Chain new redirects to EmptyChain new by default. Since a "new Chain" should be an empty one.

Since an EmptyChain link doesn't know who references it, we use a #become: to insert the new link in the chain. We could implement these two classes as a doubly linked list, but that requires more space, more management, and VisualWorks #become: is very fast. The trick in using the #become: is that we initially set the newLink's nextLink var to point back to itself. Before we do the #become:, we have another link pointing to the EmptyChain, or perhaps it really is an empty chain, and application code is referring to the EmptyChain instance as the head of the collection. And now we have a new link pointing to itself. After the #become: call, the previous link (or application code) now points to the new link, rather than the empty chain. But we also want the new link to have a nextLink that points to the original EmptyChain. Since the #become: is two way, the new link's reference to itself, is now referencing the terminating EmptyChain.

Chain #removeKey:

John Brant and Don Roberts once shared this riddle with me. "How do you delete a single link in the linked list with a pointer only to the link you want to delete?" The apparent conundrum, is that without knowing what the previous link was, how do you update its nextLink pointer to reference the nextLink of the link to be deleted. The answer is, that you don't. Instead, what you do is turn yourself (the link to be deleted) into the next link by copying its key and value to yourself, and then updating your nextLink to the be nextLink of what you just copied. So in essence what you do, is turn yourself into a clone of the next link, and then remove the now redundant nextLink from the link chain.

This ends up being a polymorphic implementation of a private method called used to #replace: aPreviousKey. The Chain implementation is easy enough:

replace: aPreviousLink
aPreviousLink setKey: key value: value next: nextLink

When we're removing the last normal link of the Chain though, the one that points to the terminating EmptyChain, that one basically does the reverse of the at:put:, using the self referential link + become: trick to change places.

replace: aPreviousLink
aPreviousLink
loopSelf;
become: self

Does it Make a Difference?

Chain and EmptyChain were a lot of fun to code up. Where I was interested in Dictionaries of sizes around 10 or less, it was a really fun way to approach the problem. I did go into this wondering about performance though. How does it stack up against normal Dictionary usage? What follows are a series of performance graphs for different dictionary APIs. In most cases I used Symbols, they have the cheapest hash and = implementations, so we don't get lost in worrying about the overhead of those. Most of the charts show results for Dictionary sizes ranging from 1 to 15.

Accessing Methods


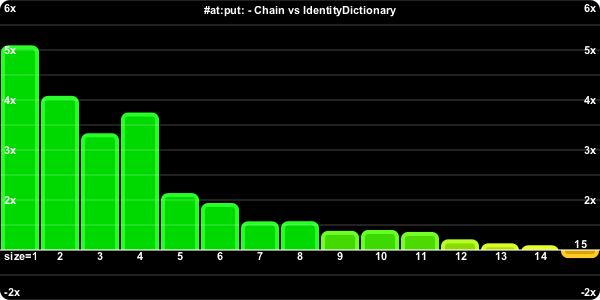
The (positive) indicates that the key was found, or in other words that the exception block was not followed. (negative) indicates the exceptional block was evaluated.

The performance for the negative path deteriorates sooner, because we have to traverse the whole chain to discover it's not there, so it becomes a function of the chain size.


There's a bit of sawtoothing to this chart. It occurs (in part) because these APIs are inherently dependent on the actual Dictionary size, for the Dictionary case. Not reported size, but the amount of memory allocated behind the scenes for a Dictionary of that size. The actual #basicSize of the 1-15 sized Dictionaries is #(3 3 7 7 7 17 17 17 17 17 17 17 37 37 37).


#size is the bane of our singly linked list. For a Dictionary, it's just a return of the tally instance variable. But the Chain has to enumerate all of its links each time to compute the current size. As the chain gets longer, it takes more and more time to compute the size.

Enumerating

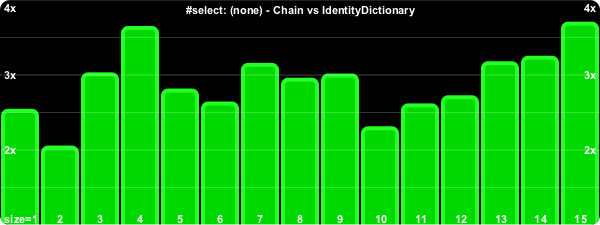
I wasn't as exhaustive with this set, I figured by now the picture was becoming clear.


#reject: is the same as #select:.

Removing

Removal is tricky to time. We need full dictionaries to remove from. It's actually the same problem as found with timing the #at:put: of initially new keys. So married the two together by measuring the time it takes to remove an existent key and then add it back.

The Chain pays a heavy price in this one because #at:put:'ing a new item involves allocating a new link, as well using #become: to insert it. As a net, that's a little slower than the IdentityDictionary which doesn't need to allocate each time.

On Beyond Dictionaries

We could do more of the Dictionary APIs, but I think the above charts are more than enough to get the picture. For things like property Dictionaries, where unique keys are determined early on, and the size is usually small, an object like Chain can offer a bit of performance boost (if you've determined you're in a speed crunch; remember "Make it Work. Make it Right. Make it Fast.").

Chain has some other interesting properties though. Unlike Dictionary, Chain can use nil as a key. And unlike Dictionary, order is preserved. At least, the order that you add the initial keys. As a Chain grows, its enumeration order doesn't change. This brings to light an interesting possibility. What if we used a Chain in place of an OrderedSet? We could make something like Chain that left the values out, or just put nil in for the values and simply use the various key APIs. For small OrderedSets we'd likely get a significant speed jump.

Why stop with OrderedSet emulation though. Dictionaries are just generalized Sequences. Or put another way, a Sequence (e.g. Array, OrderedCollection, etc) is just a special kind of Dictionary that limits its keys to a contiguous range of integers starting at 1 and ending at some size. It turns out that making Chain respond to Sequence APIs such as #first, #last, #first:, #last:, #allButFirst:, #allButLast:, #any, #fold:, #reverse, #reverseDo: is a snap.

Want an growable array that can #do faster than an array? Check this out:

In a variety of scenarios, the Chain will actually perform on par or faster with Sequences. Just don't send #size to them.

Other Thoughts


One could do a number of different things past this point. One could make different kinds of Chain subclasses for identity behavior versus equality. The trick one could use is to have the EmptyDictionary know the kind of class to use for normal links.

One could avoid the use the clever #become: trick to add and remove links, by creating private helper methods that the basic APIs called on, passing the necessary state along to do the work without resorting to clever #become: incantations.

One could play with having Chain links that stored more than one key->value pair in fixed instance variables. This would reduce the amount of link traversal via message sends relative to fixed var access, though code complexity would need to increase as it had to deal with partially populated links.

Lastly, one has to keep in mind what this exploration has been about. It's been about using fixed var access in preferences to indexed variables. And in never sending #hash to the keys, sending = only instead. The value of not using the #hash, goes down though as #hash methods get faster while = methods get slower. In other words, if you're keying with objects that have lengthy equality comparisons and fast hash comparisons, the inflection point in size where the Chain technique wins out over a traditional hash approach will shift to the left.

Tuesday, May 31, 2011

Discovering Uniscribe

I've been working on a Uniscribe interface to VisualWorks Smalltalk off and on for the last two weeks or so. One of the frustrating things for me so far, is the lack of a good post-doc resource to go to for help with this stuff. There's the MSDN docs, which are OK, but when you have questions beyond that, I have as of yet, not found any of the resources I'm used to using for this kind of thing, such as mailing lists, etc. And the amount of "tutorial" style pages out there is pretty small. So I thought I'd at least leave a trail of breadcrumbs here.

There is of course the Uniscribe Reference MSDN Docs.

Another valuable resource I found was Uniscribe: The Missing Documentation & Examples, a post written by one of the folks working on Chrome, once upon a time.

The other thing I discovered recently, is that where there are OpenType variants of UniscribeFunctions, you want to use those. For example, use ScriptShapeOpenType() instead of just ScriptShape().

Do I have a working binding between VisualWorks Smalltalk and Uniscribe? At a limited level, yes. I can deal with the standard kinds of Text emphases (#bold, #italic, #family, etc). Even #color. I'm not yet using any of the line breaking abilities (so it all comes out on one line). What can't I deal with... any string that results in more than one item. An item, in Uniscribe speak, occurs everytime the the writing system changes. So if you mix arabic and english, you get separate items for each range. But even more common, you get changes on any english punctuation. So the string 'abc,xyz' actually produces 3 items, one for the 'abc', one for the ',', and one for the 'xyz'. And currently... something isn't right with my interface when this happens. Item one is displayed correctly, but not the following items. When I figure it out, you can be sure there will be a followup post here.

Thursday, May 19, 2011

FinalizeAction

Each time I do one of these external interface things, I wrestle with the finalization problem. I have to deal with it in Cairo. In Pango. I'm currently working on Uniscribe interface, and have worked on CoreText interface. They all have this same pattern. Some external structure or opaque pointer which the library either initializes or creates for you, some functions that take the structure or opaque pointer and make stuff happen with it, and some function that frees the same. It's not enough to just use the free() interface that C provides.

The common pattern, on the Smalltalk side is that you have sort of Smalltalk object that acts as a front (facade) for your external structure/opaque pointer. And the interesting part becomes how do I make it so that when I don't need the Smalltalk object anymore, and the wonderful garbage collector makes life easy for me, erasing it from existence, that the related external resources are let go via that appropriate release/free C function.

In some part, I tried to deal with this in the Weaklings package, but the pattern is to "built on top" of the idea of weak slots. And it leaves part of the job to the programmer. Boris Popov tried to fix it in his version 18.1, but I resisted it, because it fundamentally changed the API.

I had yet another go at this in the recent ExRegex package. I don't know if this is the right solution yet, but I like it best so far. What I want is a nice simple uncomplicated, not bound up in other subclasses or frameworks, way to indicate that when an object is ready to go away, some arbitrary action happens.

The class FinalizeAction in that package, was my solution. It's a simple #ephemeron behavior (nothing to do with the ill named Ephemeron class). The ephemeral slot (the first instance variable of the an #ephemeron type object) is a reference to the object you wish to perform finalization services for. And it's other instance variable, is action. Which can be any object that responds to #value:, things like Blocks, or MessageChannels. Or even Symbols if you're using newer versions of VisualWorks (or load the simplest of all packages, SymbolValue, in older versions). What I liked about FinalizeAction was that it solved my problem with 1 class, 2 instance variables, 2 class variables, and 8 methods. Not bad. I like small solutions.

So here's some simple examples:

MessageSend
| b |
b := Pixmap extent: 10 @ 10.
"..."
(FinalizeAction for: b)
action: (MessageChannel new receiver: Transcript selector: #print:)


Block (note we're using a zero arg block which demonstrates we're actually using the cull: API)
| d |
d := ByteArray new: 100000.
"..."
(FinalizeAction for: d)
action: [ObjectMemory current spaceSummaryOn: Transcript]


Simple Unary Message Send
| f |
f := 'howdy.txt' asFilename.
"..."
(FinalizeAction for: f) action: #out


FinalizeActions have an instance registry to keep them alive until they fire. I have sought and sought for a scheme that doesn't involve some sort of registry. I thought I had one in the early part of the ExRegex spike, until the basic invariant of #ephemeron based finalization sunk in:

You have to guarantee that your finalizer will stay alive longer than the object its performing services for, and without some sort of other path back to the roots of the garbage collector, there is no way to do that.


I'm ruminating on where to go with this. Fold it into the Weaklings package? Or just clone it when I need it (given it's small size)? I'm also curious if the basic use API (as shown in the examples above) couldn't use some work to make it seem more natural. Putting a helper on Object would of course make things simpler, but I do try to keep this to a minimum.

Monday, May 16, 2011

Regex not so Regular?

A couple of days ago, on the VWNC mailing list, there was a discussion about the Regex11 package. Regex11 was originally written by Vassili Bykov as a Regex library for Smalltalk. It's actually been around a while and served the Smalltalk community pretty well, I think, in part due to Vassili's excellent coding abilities.

I think it's really cool that someone can sit down and write a complete Regex implementation in Smalltalk. This is part of the Smalltalk ethos. Being able to invent your own future. Write your own software, in any area you like. On the other hand, as I read the comments, I found myself wondering, "it's great that you can do this, but does that mean you should?" Of course, the answer varies. It depends on what your goals are. A certain part of me feels that I don't really want to care this much about how the implementation works. Isn't Regex one of those things that's grown up enough now, that we can just use off-the-shelf services provided by the host platforms? If we just reuse those, we might get some speed (benefits of thousands of code monkeys tuning and tweaking them over the years), and some standardization.

So I went on a little journey. Read on if what I discovered is of interest...

The Package

I put my work in a package called ExRegex. As in "External Regex", using the ExternalInterface features of VisualWorks to bind to an outside-of-smalltalk shared library. Plus I just liked the way ExRegex looked almost palindromic. And I made a Test package called ExRegex-Tests. No surprises here, pretty standard operating procedure.

I only began to implement the substitution stuff; for now, it's just good for matching. One thing I did do differently than Regex11 was employ a symmetric pair of binary selectors for doing Regex matches.
    '(a|b)c' ?= 'ac' --> true
'Travis' =? '(Senior|Griggs)' --> false


The ? character always leans towards the side with the regex pattern.

The Tests

I stole the tests from the Regex11-Testing package. I made my own SUnitToo copy of it. I soon found I wasn't satisfied with them. The original tests have a single test method. But said method fetches a clauseArray which is a series of inputs, and expected outputs. There's 3 or 4 relatively involved methods between the loop in the single test method and actually executing a single regex match.

What this means, is that when you get a failure, you don't know much. First you have to dig through the little framework of interpreting the clauseArray. When I'm trying to understand how someone's Regex framework works, I don't want to understand how their Regex test framework works as well. I just want to see very simple lines of code, the kind I would put in a workspace.

Secondly, as soon, as you hit a failure, you're done. The clauseArray has 137 entries in it. So if it fails for any reason (error or assertion failure) on test number 22... you have no idea how the others work. Is it just this one test? Or do others fail too? Is there a common pattern amongst the failures?

I think we forget sometimes, that just as easy as it is to write a little DSL or interpretation framework, it's just as easy to write a little bit of code that interprets that into real Smalltalk methods. It's easy to generate code and it's easy to compile it and it;s easy to install it. Here's what I did for this particular case:

RegexTest new clauseArray keysAndValuesDo:
[:index :array |
array size > 2
ifTrue:
[ws := String new writeStream.
ws
nextPutAll: 'match';
print: index.
ws nextPutAll: ' <test> '.
ws nextPutAll: ' | regex | '.
ws nextPutAll: ' regex := ' , array first printString , ' exRegex. '.
2 to: array size
by: 3
do:
[:n |
ws nextPutAll: ' self '.
ws
nextPutAll: ((array at: n + 1) ifTrue: [' assert: '] ifFalse: [' deny: ']).
ws
nextPutAll: ' (regex match: ';
print: (array at: n);
nextPutAll: ').'].
RegexTest compile: (RBParser parseMethod: ws contents) formattedCode
classified: 'tests match']]


I didn't even have to bother to format the code, I let the RB services do that for me. What I ended up with was nice easy methods to read like this:


And when I run the tests from within the IDE I get nice feedback like this:


This made it much easier to unravel things that, well, started to unravel after that.

So much for Regularity

Regularity means (among others) "conforming to a standard or pattern." I'm not sure a more ironic name was ever chosen as a moniker for a "standard set" of pattern matching. The C library interface is pretty standard. You have 4 basic functions:

  • regcomp() - builds up a regex structure based on a pattern and some flags
  • regexec() - compares an input source against the regex structure for matches
  • regerror() - makes human readable strings for your regex structure when parse errors exist
  • regfree() - used to free the various chunks of memory associated with the regfree structure

I knew Regex's varied a little from platform to platform. What surprised me was that the Regex11 did stuff the C library one couldn't (e.g. \d as sugar for [0-9] and \s for separators). And vice versa, the C library variant will do [0-9]{1,3} (match 1 to 3 digits), but the Smalltalk Regex11 can't do the {1,3} thing. You'd have to live with + (1 or more) or repeat it 3 times.

But the fun didn't stop there. While both are part of the standard libc, the BSD variant that one finds on MacOSX, is different than the one finds under GNU platforms, such as Linux. And not just in their behavior. While the 4 C functions are the same between the two, and the same symbolic defines for the flags exist, they actually map to different values. For example, the option RE_NOSUB (what you use when you just care if it matches or not, not where), is a 0x08 on a GNU platform and 0x04 on a BSD platform. And the regex_t structure, which you're responsible to allocate the memory for, is entirely different between the two. For a C program using these libraries, you just use the defines, and you're fine, but for a Smalltalk (or any other not-compiled-by-the-C-Compiler/Preprocessor language), that more intimate knowledge of what the symbolic values mean, becomes more important. Getting around these differences was interesting.

Regular? Anything but. This is kind of alarming actually. It's not like these things give you an error when you try to use something like \d. It really just tries to match an escaped d (rather than a digit), and now it fails. The upshot is that you don't have much portability with these things, and as you move from environment to environment, language to language, platform to platform, you'd better have a pretty good test suite around your regexes to make sure they're still matching the way they were when you developed your original application. On this aspect, this is one time where the "do it all in Smalltalk" actually has a compelling advantage, depending on your constraints.

There's an excellent exhaustive table at this link that shows a number of common implementations, and how they compare across a whole plethora of different options.

The Speed Factor

What about the speed issue? Again, it depends. For doing simple matches, Regex11 will come out faster. Less overhead in going across the C boundaries. Let's take a regex for matching IP addresses:
'.*(25[0-5]|2[0-4][0-9]|[01]?[0-9][0-9]?)\.(25[0-5]|2[0-4][0-9]|[01]?[0-9][0-9]?)\.(25[0-5]|2[0-4][0-9]|[01]?[0-9][0-9]?)\.(25[0-5]|2[0-4][0-9]|[01]?[0-9][0-9]?).*'.

If we match this against simple strings like '192.168.3.128' and 'abc', Regex11 is faster. As much as 3 times faster. But if we match against larger strings, such as the guts of the IPSocketAddress class>>allAboutHostAddresses method (an expected match) and the result of Object comment (shouldn't match), then the tables turn quite a bit. The Smalltalk version is suddenly 210 times slower!. This measures both the time to create the Regex object, as well as do the match.

So, I guess it depends on what kind of Regex's you're doing, and what kinds of frequencies (remember, it should always be "Make it Work, Make it Right, Make it Fast").

I don't know why exactly, the pattern above actually requires the leading and trailing .* values to match the ip patterns mid source, I had to add it for Regex11, but the ExRegex interface didn't need it.

Thursday, May 5, 2011

Easiest Example That Could Possibly Click

I'm a big fan of unit test cases. Mapped 1:1 with the objects they test (as opposed to "let's say it tests unit of functionality"). But I also write a lot of class side example methods, for the sake of prototyping, feedback, and ad hoc testing. Especially as you get into UI development, this becomes very helpful. It's hard (not impossible) to test how the pixels end up looking and interacting with unit tests.

The classic pattern you see in Smalltalk is

exampleMethod
  "self exampleMethod"

  self
    example;
    code;
    goes;
    here


Then what you do, is navigate to the method, highlight the comment and do it. If you're doing it a lot, it gets tedious to select the comment and then execute it.

So I made a simple little package called RBEasyExampleMethods, put in the repository. It makes it so you can just double click on a method in the browser, and if it looks like an example, it runs it. It looks like an example when it's

  • a class side method

  • unary (no arguments)

  • starts with 'example' OR lives in a category that starts with 'example'


It should work with VisualWorks versions from quite a ways back. Enjoy!